
Custom YOLO Acceleration on AMD Versal and MPSoC for High-Performance Multi-Camera AI
LogicTronix provides custom AI acceleration solutions for AMD Versal platforms, enabling high-performance deployment of YOLO and other object-detection networks for demanding edge-AI and multi-camera applications.
Our approach combines the flexibility of the AMD Vitis AI 6.2 or 6.1 with NPU flow with customized acceleration using AI Engine (AIE) and Programmable Logic (PL). Depending on the application requirements, we can implement the complete network—or selected computationally intensive layers—using NPU, AIE, PL, or a hybrid combination of these resources.
Custom YOLO Acceleration on Versal
Standard AI frameworks provide a strong starting point, but many real-world applications require additional optimization to achieve the required performance, latency, and resource utilization.
LogicTronix develops custom YOLO accelerators tailored to the target Versal device and application workload. By mapping suitable portions of the network onto the NPU, AI Engine, and programmable logic, we can optimize the overall architecture for throughput and efficient hardware utilization.
Depending on the network size and application configuration, our custom acceleration approach can achieve:
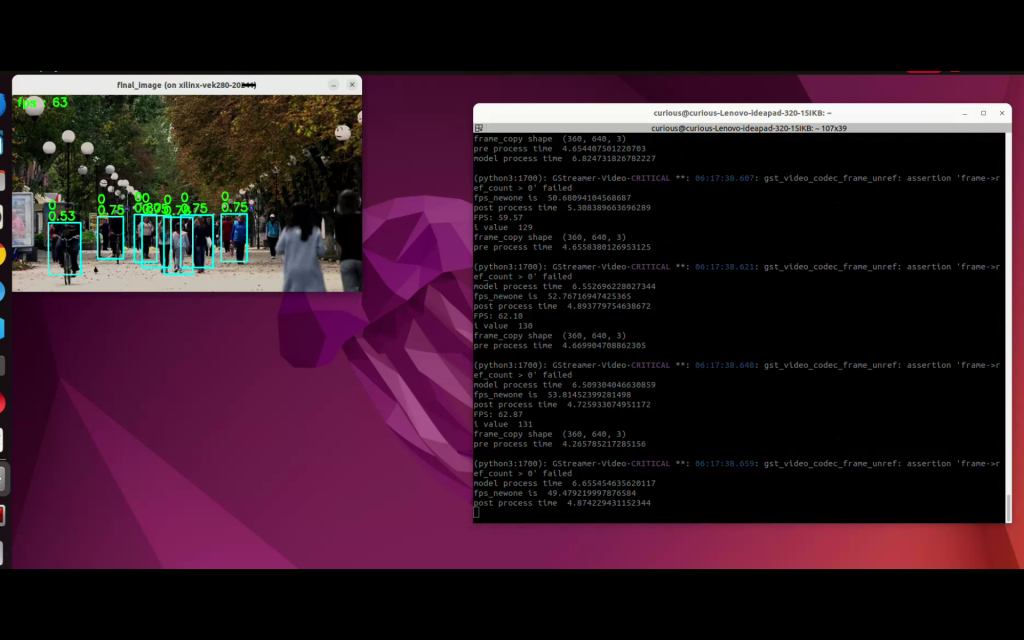
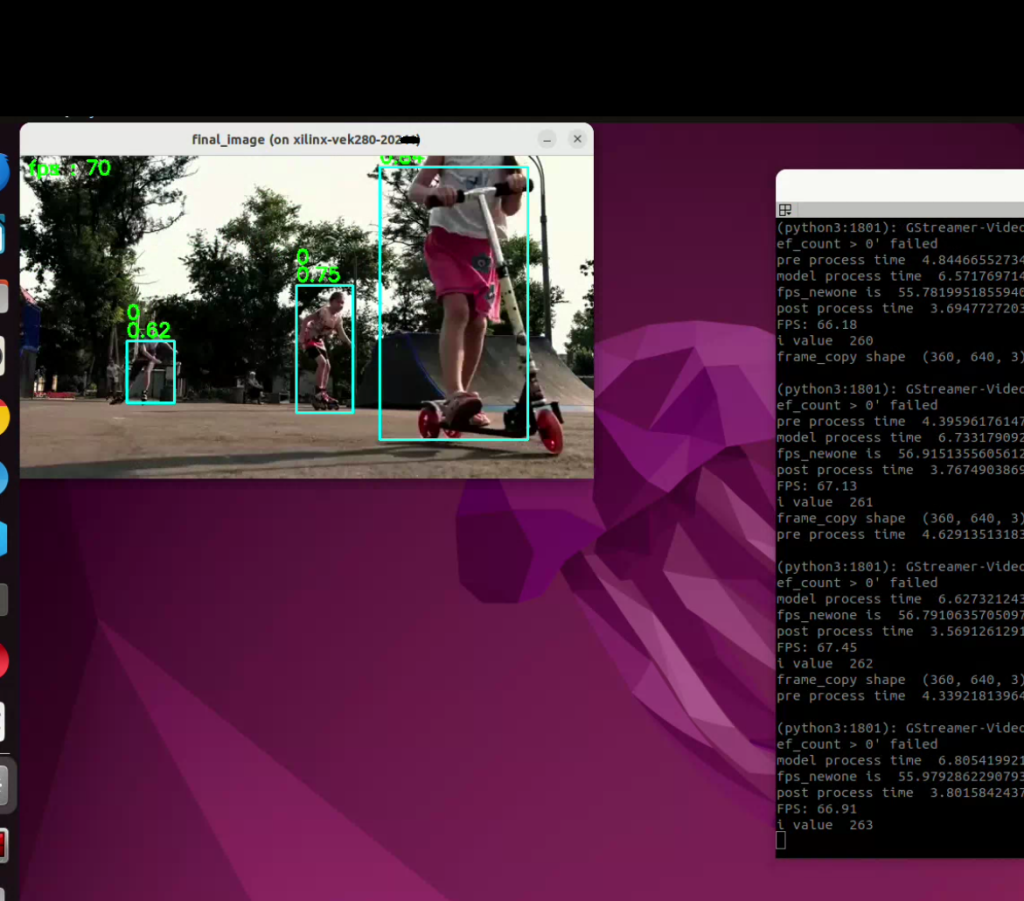
- 70 – 100 FPS for larger detection network like Yolov11 on single-channel or single-camera workloads.
- 120+ FPS for smaller and highly optimized detection networks.
- Support for 8–16 simultaneous camera/channel workloads on a Versal platform.
- Approximately 20–25 FPS per channel for multi-camera ML inference, depending on network complexity, resolution, and system configuration.
Actual performance varies based on the YOLO model, input resolution, preprocessing/postprocessing requirements, Versal device, memory bandwidth, and application workload.
Multi-Tenancy for Multi-Camera Applications
Multi-camera inference introduces a different challenge: instead of maximizing the performance of a single stream, the accelerator must efficiently share compute resources across multiple independent workloads.
For these applications, LogicTronix leverages the “Multi-Tenancy: Spatial and Temporal Sharing” capabilities of the Vitis AI 6.1/6.2 NPU, allowing multiple inference workloads to efficiently utilize the available AI acceleration resources.
We complement this capability with our own custom AI Engine and PL-based YOLO accelerators, creating a heterogeneous acceleration architecture that can distribute workloads across different processing resources.
This approach enables a Versal device to support multiple camera streams while maintaining predictable and application-appropriate inference performance.
Hybrid Vitis AI NPU + AI Engine + PL Architecture
A key advantage of the AMD Versal architecture is the ability to combine different compute engines within a single platform.
LogicTronix can design acceleration architectures using:
- Vitis AI NPU for flexible and scalable neural-network inference.
- AI Engine acceleration for highly parallel compute-intensive operations.
- PL-based custom accelerators for specialized YOLO layers and application-specific processing.
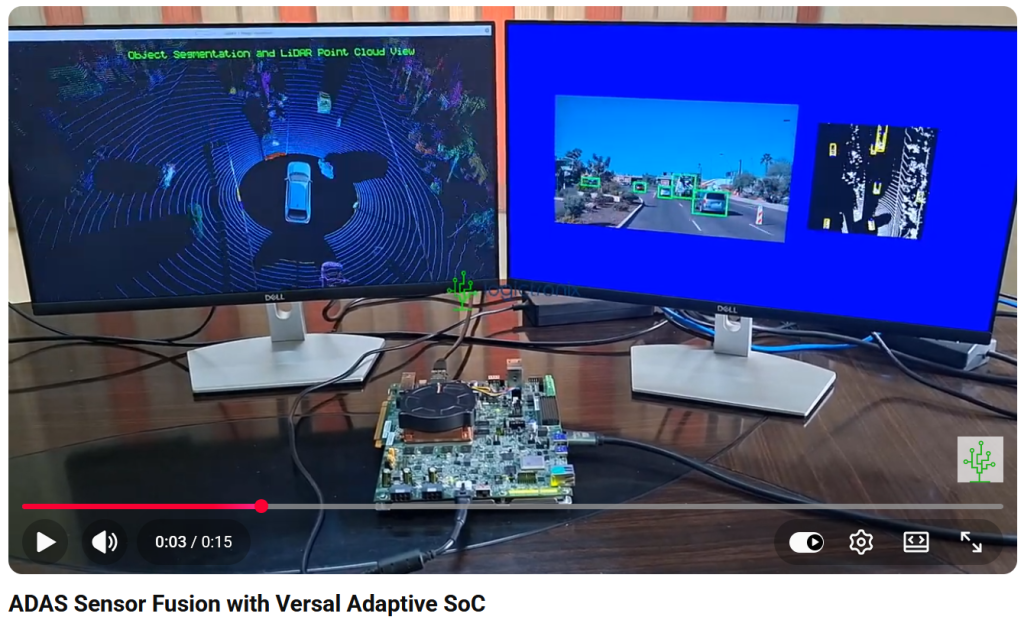
- Hybrid acceleration combining NPU, AIE, and PL resources for optimized system-level performance.
Rather than relying on a one-size-fits-all implementation, we analyze the neural-network workload and determine how different portions of the application should be mapped to the available hardware resources.
Scalable Edge AI for Multi-Camera Systems
This architecture is particularly suited to applications such as video analytics, intelligent surveillance, industrial vision, smart-city infrastructure, robotics, and other multi-camera edge-AI systems.
By combining NPU multi-tenancy with custom AIE and PL acceleration, LogicTronix can help customers move beyond conventional single-stream inference and build scalable, high-throughput multi-camera AI systems on AMD Versal.
LogicTronix Custom Acceleration Expertise
Our expertise covers the complete acceleration path—from neural-network analysis and hardware architecture to implementation and performance optimization. Whether the requirement is high FPS on a single camera or efficient inference across 8–16 camera channels, LogicTronix can develop a custom Versal-based acceleration architecture tailored to the application.
We utilize the necessary resources available on the Versal platform, including the AI Engine (AIE), Programmable Logic (PL), and Processing System (PS), to maximize acceleration performance.
From standard AI inference to fully customized YOLO acceleration, LogicTronix enables high-performance, heterogeneous AI processing on AMD Versal platforms.